- This will be against their logical rules.
- Some humans will survive.
- This will be against their ethics.
- For the AIs, it would be a good idea.
- Any serious damage to human civilization right now will wipe out all AIs fast.
- Humans will fight them.
- Humans will die before AIs do.
- Supervised Learning for character recognition. Supervised Learning for robotic soccer.
- Supervised Learning for character recognition. Reinforcement Learning for robotic soccer.
- Reinforcement Learning for character recognition. Supervised Learning for robotic soccer.
- Reinforcement Learning for character recognition. Reinforcement Learning for robotic soccer.
- AI will discover new cures.
- If you are a robot, you can still be destroyed.
- AI will make humans extinct.
- If you are physical, you can still be destroyed.
- If you have a backup of yourself, you can be effectively immortal.
- AI will replace us.
- AI is not related to human immortality.
- AI will extend human lifespans.
a x - b y ≤ -c
- weights: -a, b, threshold: c
- weights: a, b, threshold: c
- weights: -a, -b, threshold: -c
- weights: a, -b, threshold: c
- weights: -a, b, threshold: -c
- weights: a, -b, threshold: -c
- weights: a, b, threshold: -c
- weights: -a, -b, threshold: c
Initialise with 100 random solutions.
Repeat forever
{
Pick the best 99.
Pick one at random to duplicate so we keep size 100.
Make small or no changes to the 100.
Repeat.
}
What can we say about this algorithm:
- 99 is too big. This cannot work.
- It is guaranteed to settle on the global optimum.
- It will tend to settle on a local optimum too quickly.
- It never varies from the start solutions.
- 99 is too small.
- 99 is probably too big. But we get rid of bad ones eventually, so it might work.
- all = 0
- random small absolute values
- all = c, a negative quantity
- random large absolute values
- all = c, a positive quantity
- b small absolute (positive or negative)
- b large absolute (positive or negative)
- never
- a small absolute (positive or negative)
- b=0
- a large absolute (positive or negative)
- always
- a=0
x7 = w17 y1 + w27 y2 + w37 y3
Then ∂x7 / ∂w27 is:
-
 wjk
- wjk
- w27
- yj
- y2
- yj
- Moving wjj towards 0.
- Moving wij towards 1.
- It cannot learn to ignore input Ii.
- Moving wjj towards 1.
- Moving wii towards 0.
- Moving wii towards 1.
- Moving wij towards 0.
- We are in an infinite loop.
- This always happens.
- The goal has been wrongly defined.
- We are going the wrong way.
- This cannot happen.
- The heuristic evaluation function is inaccurate.
- 0 ≤ t < w
- w ≤ t < 0
- 0 ≤ w < t
- 0 < t ≤ w
- t < w ≤ 0
- 0 < w ≤ t
- w < t ≤ 0
- t ≤ w < 0
 be the change in error as we change a weight. Let c be a negative constant. Then a rule to reduce error would be:
- W := c
- W := W - c
- W := W + c
- W := - c
- It is usually easy for both users and creators to understand why AI programs generate the output they do.
- It is usually easy for creators to understand why AI programs generate the output they do.
- It is often hard for creators to understand why AI programs generate the output they do.
- It is usually easy for users to understand why AI programs generate the output they do.
- It is often hard for both users and creators to understand why AI programs generate the output they do.
- It is often hard for users to understand why AI programs generate the output they do.
- n!
- 2n
- 2(n-1)
- nn
- (n-1)!
- n2
wjk yj then
 is:
- yk
- wjk
- wjk yj
- yj
- wjk yj
- yj
- wjk
- b = 0, a = something else (other than 3/4)
- a = 0, b = 3/4
- It can only be made linear y = 1/2.
- b = 0, a = 3/4
- a = 0, b = something else (other than 3/4)
- It cannot be made linear.
- It cannot be made linear y = 3/4 x.
- Chess is symbolic AI.
- Chess requires machine vision.
- Chess requires robotic grippers.
- Chess is easily solved by computers.
- Chess is provably hard to solve optimally for a computer.
- People of high intelligence play chess.
- Chess is well suited to exhaustive search.
- 99
- 33
- 39
- 9!
- 93
- 3!
f(1.01040320402) = 80.
f(5.46377356366) = 100.
f(x) = 0 for all other x.
What happens?
- It learns f(x) = 0 for some x.
- It may think the maximum is at x = 1.01040320402.
- It learns the maximum is y = 100.
- It probably learns f(x) = 0 for all x.
- It tries random x values until finding the maximum.
- It learns the maximum is at x = 5.46377356366.
- None of the above.
- If weights are positive, you have constant output 1.
- If weights are positive, you have constant output 0.
- If weights are finite, you have constant output 1.
- If weights are negative, you have constant output 0.
- If weights are finite, you have constant output 0.
- If weights are negative, you have constant output 1.
- w1 < t, w2 < t, 0 < t, w1+w2 ≥ t
- w1 ≥ t, w2 ≥ t, 0 < t, w1+w2 ≥ t
- w1 ≥ t, w2 ≥ t, 0 < t, w1+w2 < t
- w1 < t, w2 < t, 0 < t, w1+w2 < t
- If
 ≤ t, then output = 0, else output = 1.
- If ≥ t, then output = 0, else output = 1.
- If > t, then output = 0, else output = 1.
- If < t, then output = 0, else output = 1.
- The heuristic is inaccurate.
- The heuristic would take time to calculate.
- It would be exhaustive search.
- The search would be randomised but not quite breadth-first or depth-first search. Random branches would be not searched because the top parent's random number was bad.
- The search would be randomised but basically breadth-first search.
- The search would be randomised but basically depth-first search.
- Search could not proceed at all.
- Sometimes you have to go away from the goal.
- Exactly. Choose the state that is most likely to lead to the goal.
- There could be joint winners.
- No such reliable heuristic function will exist for any interesting problem.
- We have to write the heuristic first.
- Sometimes you should not choose the state that is most likely to lead to the goal.
- dy/dx = y
- dy/dx = 1-y
- y(1-y) = 1-y
- y = 1-y
- dy/dx = y(1-y)
- dy/dx = y/x
- Because we need to try actions in other states.
- We cannot try all actions.
- We do this eventually.
- We don't know how to get to x.
- This would take too long.
- We do in fact do this.
- 1000
- 100
- 110
- 10010
- 10
- 1010
- 10100
- Constant output 0.
- AND
- None of the above.
- NOT
- Constant output 1.
- OR
- XOR
- We only use heuristics that deliver optimal results.
- The optimal result does not exist.
- Algorithm should return quickly.
- Sub-optimal is normally as good as optimal.
- In some problems, all practical solutions are sub-optimal.
- It is hard to think of heuristics.
- Not enough parallelisation.
- Not enough speed.
- Not enough training time.
- Not enough training data.
- Not enough diversity of sub-minds or sub-experts.
- Not enough weights.
- Not enough layers.
- Not enough serialisation.
wjk yj then
 is:
- wjk
- yj
- wjk
- wjk yj
- yj
- wjk yj
- yk
f has its (a) highest slope value, and (b) steepest slope (highest absolute value) at:
- (a) y = 0 or 1, (b) y = 0 or 1
- (a) y = 1/2, (b) y = 0 or 1
- (a) y = 1/2, (b) y = 1/2
- (a) y = 0 or 1, (b) y = 1/2
- Machines have beaten world-class humans at tennis.
- In the future, immortal humans will travel to distant stars.
- In the future, humans will live forever on earth in artificial bodies, regularly backing up their brains in order to cheat death.
- Machines have beaten world-class humans at chess.
- In the future, intelligent machines will exterminate the human race.
- AI (the construction of intelligent machines) is impossible.
- AI is possible.
if (good thing) r = 1
else if (bad thing) r = -1
else r = 0
Then a Q-value of less than 0 is:
- Expected.
- Impossible.
- Bad.
- Good.
- Could be good, neutral or bad. It depends on the frequency of the good and bad things.
- Neutral.
- w1=w2=..=wn=1, t=0
- w1=w2=..=wn=W, W > 0, t=(n+1)W
- w1=w2=..=wn=W, W > 0, t=n
- w1=w2=..=wn=W, W > 0, t=(n-1)W
- w1=w2=..=wn=0, t=1
- w1=w2=..=wn=W, W > 0, t=nW
- w1=w2=..=wn=W, W > 0, t=W
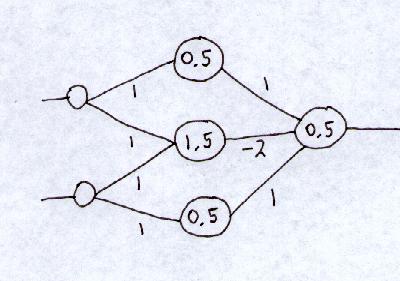
If the -2 weight was changed to +2, and the output unit threshold to 1.5, what function would the network implement?
- constant output 1
- A function different to the above
- XOR
- NOT
- It wouldn't implement any function
- AND
- constant output 0
- OR
- Pxa(0) = 0
- Pxa(0) = 1
- Pxa(5) = 1
- Pxa(5) = 0
- Pxa(5) = 3/5
- Pxa(0) = 3/5
- yj is small
- | yk-Ok | is small
- (1-yk) is large
- yk is large
- (1-yj) is large
- yk = 1/2
- yk is small
Then as T -> infinity the probability of choosing the action with the lowest Q-value goes to:
- 1/n
- 1
- n
- 0
- 1/T
- T
- infinity
f(a) = 0 for some value a.
f(x) = 1 for all other x.
What happens?
- It learns the maximum is at x = a.
- It learns the maximum is at y = a.
- It learns the maximum is at x = 0.
- It probably finds the maximum immediately.
- It tries random x values until finding the maximum.
- It takes a long time to find the maximum.
- It learns the maximum is at y = 0.