- Yes. But a heuristic can be used to eliminate all bias.
- Yes. But a heuristic can be used to produce a bias that is better than random.
- Yes. But it is never a problem.
- Yes. But it is rarely a problem.
- Nodes on the left are not searched first.
- No.
- Yes. But it is alright because all nodes will be searched eventually.
- Best-first search will eliminate all bias.
- We find that f(x) = 1 for all x.
- We search until we find one of the seven values.
- We find that f(x) = 1 for some x.
- We will find the maximum quickly.
- We find the maximum is where f(x) = 1
- We find the maximum is where f(x) = 10
- w1 ≥ t, w2 ≥ t, 0 < t, w1+w2 < t
- w1 < t, w2 < t, 0 < t, w1+w2 ≥ t
- w1 < t, w2 < t, 0 < t, w1+w2 < t
- w1 ≥ t, w2 ≥ t, 0 < t, w1+w2 ≥ t
- It will not run on any client.
- It cannot be downloaded.
- The pricing does not allow downloading.
- It cannot be downloaded and it will not run on any client.
- It will not run locally unless it is in JavaScript.
- We do not use it through an API.
- We do not use it through a web page.
- Learning it from exemplars is impossible.
- Learning it from exemplars is impossible for some values of x.
- What is the point? That is choosing an inaccurate representation when an accurate one is available.
- We would use a neural network, and learn it from exemplars.
- It would take too long.
- It is a chaotic function.
- Divide by zero error.
That is, A NOR B = 1 if and only if A = 0 and B = 0.
The set of inequalities that define a perceptron to implement NOR are:
- 0 < t, w1 > t, w2 > t
- 0 > t, w1 ≤ t, w2 ≤ t
- 0 > t, w1 < t, w2 < t
- 0 ≥ t, w1 < t, w2 < t
- 0 < t, w1 ≥ t, w2 ≥ t
- 0 ≤ t, w1 > t, w2 > t
- 0 ≤ t, w1 ≥ t, w2 ≥ t
- 0 ≥ t, w1 ≤ t, w2 ≤ t
- The heuristic is inaccurate.
- Search could not proceed at all.
- The search would be randomised but basically depth-first search.
- It would be exhaustive search.
- The heuristic would take time to calculate.
- The search would be randomised but basically breadth-first search.
- The search would be randomised but not quite breadth-first or depth-first search. Random branches would be not searched because the top parent's random number was bad.
f(a) = 0 for some value a.
f(x) = 1 for all other x.
What happens?
- It learns the maximum is at x = 0.
- It learns the maximum is at y = a.
- It learns the maximum is at y = 0.
- It takes a long time to find the maximum.
- It learns the maximum is at x = a.
- It tries random x values until finding the maximum.
- It probably finds the maximum immediately.
- The heuristic becomes highly inaccurate.
- It depends what c is.
- The heuristic stops working.
- It works exactly the same.
- If c=0 it is fine.
- The heuristic becomes somewhat inaccurate.
- w1=w2=w3=0, t=3
- w1=w2=w3=1, t=3
- w1=w2=w3=1, t=0
- w1=w2=w3=0, t=1
- w1=w2=w3=1, t=1
- w1=w2=w3=0, t=0
f(1.01040320402) = 80.
f(5.46377356366) = 100.
f(x) = 0 for all other x.
What happens?
- It learns the maximum is at x = 5.46377356366.
- It may think the maximum is at x = 1.01040320402.
- It learns f(x) = 0 for some x.
- It tries random x values until finding the maximum.
- It probably learns f(x) = 0 for all x.
- It learns the maximum is y = 100.
- Anything. (The outputs are all the same number, but it can be any number.)
- 1
- 0
- Anything. (The outputs can all be different.)
- 1/2
- -infinity
- infinity
- We draw a partial state-space representation of the problem.
- Writing a program to automatically draw it.
- Using symmetry to reduce the size of the state-space.
- It is not solved. We do not draw the state-space representation of the problem.
- Using a heuristic to reduce the size of the state-space.
- Doing a truncated search.
- If weights are negative, you have constant output 0.
- If weights are positive, you have constant output 1.
- None of the above.
- If weights are negative, you have constant output 1.
- If weights are finite, you have constant output 0.
- If weights are positive, you have constant output 0.
- If weights are finite, you have constant output 1.
- AI will discover new cures.
- AI is not related to human immortality.
- If you are a robot, you can still be destroyed.
- If you have a backup of yourself, you can be effectively immortal.
- AI will make humans extinct.
- If you are physical, you can still be destroyed.
- AI will replace us.
- AI will extend human lifespans.
An example showing that this is this a bad measure of the error is: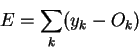
- y = (0,1,1,1,0,0), O = (0,0,0,0,1,0)
- y = (0,1,1,1,0,0), O = (0,1,1,1,0,0)
- y = (0,1,1,1,0,0), O = (0,0,0,0,1,1)
- y = (0,1,1,1,0,0), O = (1,0,0,0,1,1)
- AIs keep improving in accuracy every year.
- AI can run the task thousands of times in a short period.
- AI can run the task thousands of times without getting tired.
- Maybe no other AI system is better than 95%.
- Human might be hard to find.
- Human is expensive.
 wjk yj
then
 is:
- wjk yj
- wjk
- wjk yj
- wjk
- yk
- yj
- yj
- Humans do not operate according to logic.
- Humans do not run algorithms.
- Humans cannot search the entire search space.
- Humans cannot search the partial search space.
- Humans do not explicitly store all their memories.
- Humans are not machines.
- Humans cannot compare different solutions in the search space.
- Humans do not implicitly store all their memories.
- The best human does not do exhaustive search.
- Chess programs do exhaustive search, if they are given enough time.
- They cannot beat the best human.
- Chess programs do exhaustive search.
- Exhaustive search is not needed to find the global optimum move.
- The best human does exhaustive search.
- You could not get a billion people to instantiate a computer.
- You could not talk to the people in English if they do not know English.
- Yes. Exactly.
- The program would take too long to work.
- The program would take too much space to work.
- The program cannot work if people do not understand the English input.
- This will be against their ethics.
- For the AIs, it would be a good idea.
- Some humans will survive.
- Humans will die before AIs do.
- Any serious damage to human civilization right now will wipe out all AIs fast.
- This will be against their logical rules.
- Humans will fight them.
- There are 10 sub-spaces of the input space that map to the characters. The sub-spaces are well-defined. They do cover the entire input space.
- There are 10 sub-spaces of the input space that map to the characters. The sub-spaces are well-defined. They do not cover the entire input space.
- The input space is divided into 10 poorly-defined sub-spaces.
- There are 10 sub-spaces of the input space that map to the characters. The sub-spaces are not well-defined. They do not cover the entire input space.
- There are 10 sub-spaces of the input space that map to the characters. The sub-spaces are not well-defined. They do cover the entire input space.
- The input space is divided into 10 well-defined sub-spaces.
If h(x) = 1 then are we close to the goal?
- Yes, if the heuristic is accurate.
- h has no correlation with closeness to goal.
- Yes of course. Only one piece is out of place.
- h(x) cannot be equal to 1.
- On average, probably yes. But there are some configurations where h(x) = 1 and we are far from the goal.
- Yes.
- Probably no.
- No.
y = ς(x) = 1 / ( 1 + e-x )How would you make it less step-like (more linear)?
- ς(10x)
- ς(x-10)
- ς(-x/10)
- ς(x/10)
- ς(x+10)
- ς(-10x)
a x + b y = cDefine a perceptron that receives x and y as input and fires if and only if the point is on this side of the line:
a x + b y ≤ c
- weights: -a, -b, threshold: c
- weights: a, b, threshold: -c
- weights: -a, b, threshold: -c
- weights: a, b, threshold: c
- weights: -a, -b, threshold: -c
- weights: a, -b, threshold: -c
- yk is small
- yk = 1/2
- yj is small
- yk is large
- (1-yk) is large
- (1-yj) is large
- | yk-Ok | is small
Then for any individual output node k,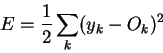
 is:
-
 yk (1-yk)
- (yk-Ok)
- yk (1-yk) (yk-Ok)
- 1/2 (yk-Ok)
- (yk-Ok)
- yk (1-yk)
- 33
- 99
- 9!
- 39
- 3!
- 93
 be the change in error as we change a weight. Let c be a positive constant. Then a rule to reduce error would be:
- W := c
- W := W - c
- W := - c
- W := W + c
- 102 n
- 102 n + 1
- 100 n
- 101 n + 1
- 100 n + 1
- 101 n
- 100 + n
- 101 + n
- They have rules that evolved over time, that people agree are good rules to decide the winner.
- Solving them leads to prize money.
- AIs can win them.
- There is funding to solve them.
- They get lots of media coverage.
- AIs think faster than humans so can beat them.
- The public loves games and sports.
- Yes because a heuristic is only a guess.
- No, because heuristic is better than random.
- No. The whole point of random is it is the worst strategy.
- Yes, but only if the heuristic bizarrely gives the worst suggestions not the best ones.
- Yes. And normally would be.
- No. Never.
a x - b y ≤ -c
- weights: a, b, threshold: -c
- weights: -a, -b, threshold: -c
- weights: -a, b, threshold: c
- weights: -a, b, threshold: -c
- weights: a, -b, threshold: -c
- weights: a, -b, threshold: c
- weights: -a, -b, threshold: c
- weights: a, b, threshold: c
Initialise with 100 random solutions.
Repeat forever
{
Pick the best 99.
Pick one at random to duplicate so we keep size 100.
Make small or no changes to the 100.
Repeat.
}
What can we say about this algorithm:
- 99 is too small.
- It is guaranteed to settle on the global optimum.
- 99 is probably too big. But we get rid of bad ones eventually, so it might work.
- 99 is too big. This cannot work.
- It never varies from the start solutions.
- It will tend to settle on a local optimum too quickly.
- 1000
- 10100
- 1010
- 10010
- 100
- 110
- 10
y = ς(x) = 1 / ( 1 + e-x )How would you make it more step-like (more like a sudden threshold)?
- ς(x+10)
- ς(10x)
- ς(x-10)
- ς(x/10)
- ς(-10x)
- ς(-x/10)
- Sub-Symbolic AI tackling Symbolic AI problems.
- Symbolic AI tackling Symbolic AI problems.
- Sub-Symbolic AI tackling Sub-Symbolic AI problems.
- Symbolic AI tackling Sub-Symbolic AI problems.
- 12.
- 13.
- 37.
- 24.
- 1.
- 14.
- 38.
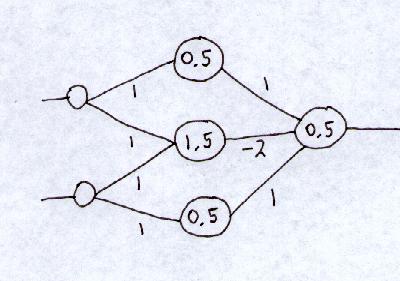
What function does this network implement?
- A function different to the above
- XOR
- It wouldn't implement any function
- OR
- NOT
- AND
- constant output 1
- constant output 0